
What Is FairyScanner-OCR Scan & Reader IPA?
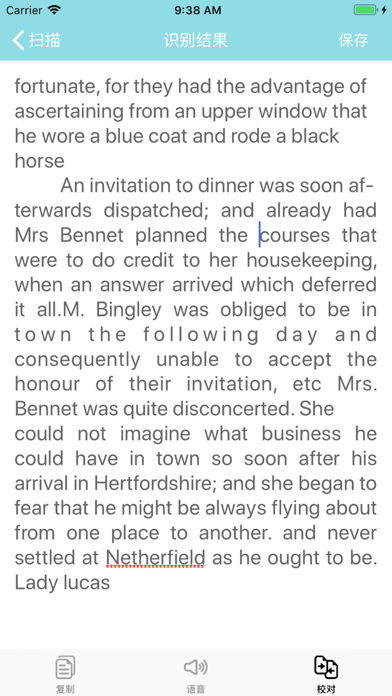
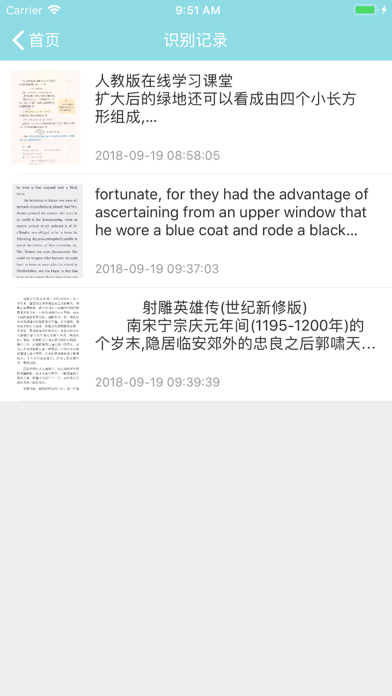
FairyScanner-OCR Scan & Reader IPA is the iOS package for a tool that turns text in images into editable text and supports spoken reading. This page provides version 2.5. The developer describes recognizing a photographed page or picture, reviewing the recognized text, and using voice features with several languages. Its practical appeal is the connection between capture, correction, and listening: a passage on paper can become material that is easier to edit or hear on a phone. Recognition is not guaranteed to be exact, so proofreading remains part of the workflow. This guide explains how to prepare a readable image, check the result, and use audio without treating an automated transcription as an unquestionable copy.
Capture the page with recognition in mind
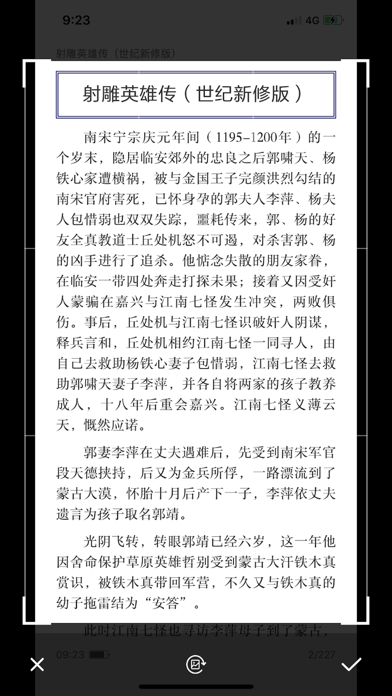
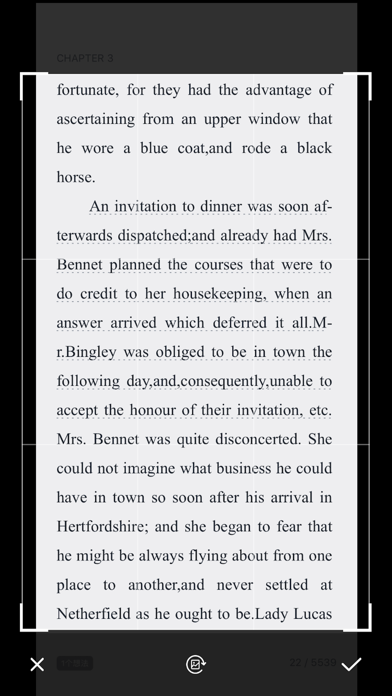
A useful scan begins with a clear source image. Place the page flat, keep the phone steady, and use even light that does not create glare across important words. Try to keep the page reasonably square to the camera and include the complete passage needed for the task. Small text, a curved book page, and a strong shadow can each make recognition harder. Inspect the image before moving away from the source so a poor capture can be repeated immediately. This step can save more time than correcting a long sequence of avoidable recognition errors. The app works from what the image shows, so a better input remains valuable even when the recognition system is capable.
Choose the passage rather than importing unnecessary material
If the task concerns one paragraph, consider whether the image includes unrelated columns, captions, or private notes. A crowded page can make reading order difficult to interpret. Use the capture or cropping options actually available in the installed build to keep the relevant material clear. Preserve the complete original separately when it matters for context or later review. A focused working image can be easier to proofread without losing the source record. This is especially useful for a page with sidebars or a layout that does not follow a simple left-to-right sequence. The aim is a clear relationship between the picture and the text you intend to extract.
Proofread names, numbers, and unusual characters first
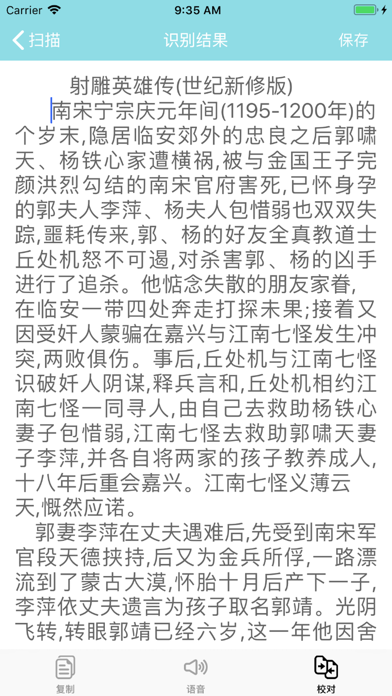
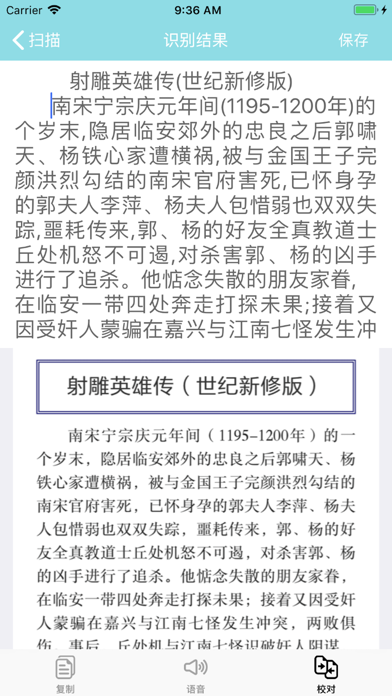
A recognized passage can look fluent while containing a small but important error. Pay particular attention to names, dates, reference numbers, punctuation, and characters that resemble one another. Compare them directly with the image rather than relying only on whether the sentence sounds plausible. An incorrect digit can be more consequential than a misspelled ordinary word. If the text will be used in a form, a report, or another important document, review the relevant details carefully before sharing. Automated recognition is a convenience for transferring material, not a guarantee that the transfer is complete. Keeping the source image available makes that verification much easier.
Check the order of a complex page
Books, magazines, and documents can contain multiple columns, headings, footnotes, or text around images. After recognition, read the result in sequence and check whether the paragraphs appear in the intended order. A system may recognize individual words correctly while arranging them in a confusing way. Repair the structure before using the text for further editing or spoken reading. If the page is particularly complex, several focused captures may be easier to manage than one large image. Give each section a clear place in the final document. The useful result is readable text that preserves the source's meaning, rather than a collection of correctly recognized fragments with an uncertain relationship to one another.
Edit a working copy while preserving the source
Once recognition is complete, separate transcription corrections from deliberate rewriting. Correct a misread word to match the source first; make any later summary or adaptation in a clearly identified copy. This distinction matters when the text will be quoted, studied, or compared with the original. Keep a descriptive name for the working document so it is easy to find again. If the app provides export or sharing options, inspect the result outside the editor and confirm that line breaks and characters remain sensible. A good transfer process leaves both a recoverable source and an understandable edited file, with no need to guess which changes were made by recognition and which were made intentionally.
Use spoken reading after checking the text
The developer describes turning recognized text into voice. Listening can be useful for reviewing a passage or accessing material in another way, but a voice will also read recognition errors unless they are corrected. Test a short section and choose the language and reading settings available in the installed version. Listen for names, abbreviations, and punctuation that may be spoken unexpectedly. Adjust the text or settings where appropriate, while preserving an accurate written copy. Audio is most helpful when it supports a clear passage, rather than masking an uncertain transcription. A natural-sounding voice does not establish that the underlying words or their order match the original page.
Review language and privacy requirements separately
The current listing mentions several languages and pronunciations. Check the actual language options and recognition behavior in the installed build before relying on it for a particular document. A page containing several languages may need more careful review than a simple passage in one language. Also understand how the app handles image and voice processing before using sensitive material. Allow photo or camera access only as needed for the intended task, and choose sharing destinations deliberately. A scanned page may include an address, account detail, or another person's information outside the passage you meant to capture. Convenience should not make that surrounding material invisible during review.
FairyScanner-OCR Scan & Reader IPA for iPhone
This FairyScanner-OCR Scan & Reader IPA for iPhone is version 2.5. Confirm compatibility and preserve valuable source images and corrected text outside the app before replacing another installation. After opening it, test a short, non-sensitive page from capture through recognition, correction, and spoken reading. The IPA does not establish paid access, online processing availability, or perfect recognition for every language and layout. Features in the current store listing may differ from the installed build. A matching file identity confirms which package is provided, while the practical result still depends on image quality, language selection, and a careful comparison with the source.
Make the final text easy to trust and reuse
Before considering a task complete, identify what the output is meant to support. A personal reading aid, a study note, and a passage to be reproduced elsewhere can require different levels of checking. Keep attribution and permission requirements in mind when reusing material, and avoid presenting an uncertain transcription as an exact quotation. Name the final file clearly and retain enough context to find its source later. FairyScanner is most useful when it shortens the mechanical work of transferring text while leaving room for deliberate review. The strongest outcome is editable, readable material whose important details have been checked, with audio serving as another useful way to engage with the corrected passage.